Anh-Quan Cao - Research Scientist in 3D Perception and Autonomous Driving

Anh-Quan Cao

I am a Research Scientist at Valeo.ai, working on 3D perception for autonomous driving.

I completed my PhD in the ASTRA-Vision group at Inria, under the guidance of Raoul de Charette. Prior to this, I earned an MSc in Artificial Intelligence & Advanced Visual Computing from École Polytechnique, an MSc in Data Science from University of Paris-Saclay, and a BSc in Computer Science from University of Science and Technology of Hanoi (USTH).

Email Scholar Github

News

09/2026 VATIX wins the Runner-up Best Paper Award at the ECCV 2026 DriveX Workshop.
09/2026 Outstanding reviewer at CVPR 2026 and ECCV 2026.
02/2026 StableMTL, OccAny, DrivOR are accepted at CVPR 2026.
11/2025 Outstanding reviewer at WACV, CVPR, ICCV 2025; Top reviewer at NeurIPS 2025.
06/2025 StableMTL is available on arXiv.
01/2025 Start a new position as a Research Scientist at Valeo.ai.
12/2024 I defended my PhD thesis.
09/2024 Outstanding reviewer at CVPR and ECCV 2024.
05/2024 PaSCo is selected by CVPR 2024 as best paper award candidate.
Publications

How Far Can 5,500 Hours of Driving Take You? A Scaling Law Analysis of Video Diffusion Models

Victor Besnier, Anh-Quan Cao, Elias Ramzi, Spyros Gidaris, Tuan-Hung Vu, Andrei Bursuc, Éloi Zablocki, Matthieu Cord
ECCV 2026 DriveX Workshop
Oral, Runner-up Best Paper Award

TL;DR: A scaling-law study of video diffusion models trained from scratch on 5,500 hours of driving, from 1M to 9B parameters, whose 9B model sets a new open-source state of the art on nuScenes.

OccAny: Generalized Unconstrained Urban 3D Occupancy

Anh-Quan Cao, Tuan-Hung Vu
CVPR 2026

TL;DR: A generalized urban 3D occupancy model that works on uncalibrated, out-of-domain scenes and predicts metric occupancy from monocular, sequential, or surround-view inputs.

DrivOR: Driving on Registers - Lightweight Transformer for End-to-End Driving

Driving on Registers

Ellington Kirby, Alexandre Boulch, Yihong Xu, Yuan Yin, Gilles Puy, Éloi Zablocki, Andrei Bursuc, Spyros Gidaris, Renaud Marlet, Florent Bartoccioni, Anh-Quan Cao, Nermin Samet, Tuan-Hung VU, Matthieu Cord
CVPR 2026

TL;DR: A lightweight transformer for end-to-end driving that compresses multi-camera features with register tokens and improves efficiency without sacrificing trajectory quality.

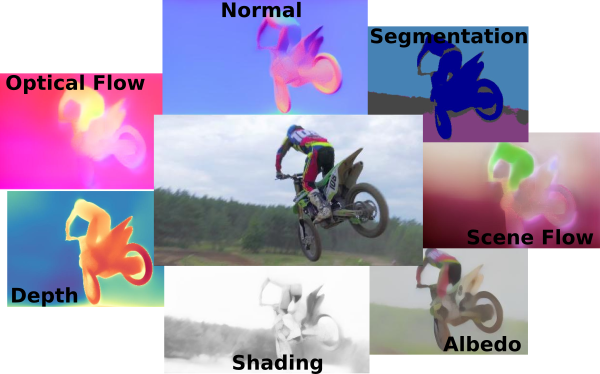
StableMTL: Multi-Task Learning from Partially Annotated Synthetic Datasets

StableMTL: Repurposing Latent Diffusion Models for Multi-Task Learning from Partially Annotated Synthetic Datasets

Anh-Quan Cao, Ivan Lopes, Raoul de Charette
CVPR 2026

TL;DR: Reuses latent diffusion priors for multi-task learning on partially annotated synthetic data, improving label efficiency and task performance.

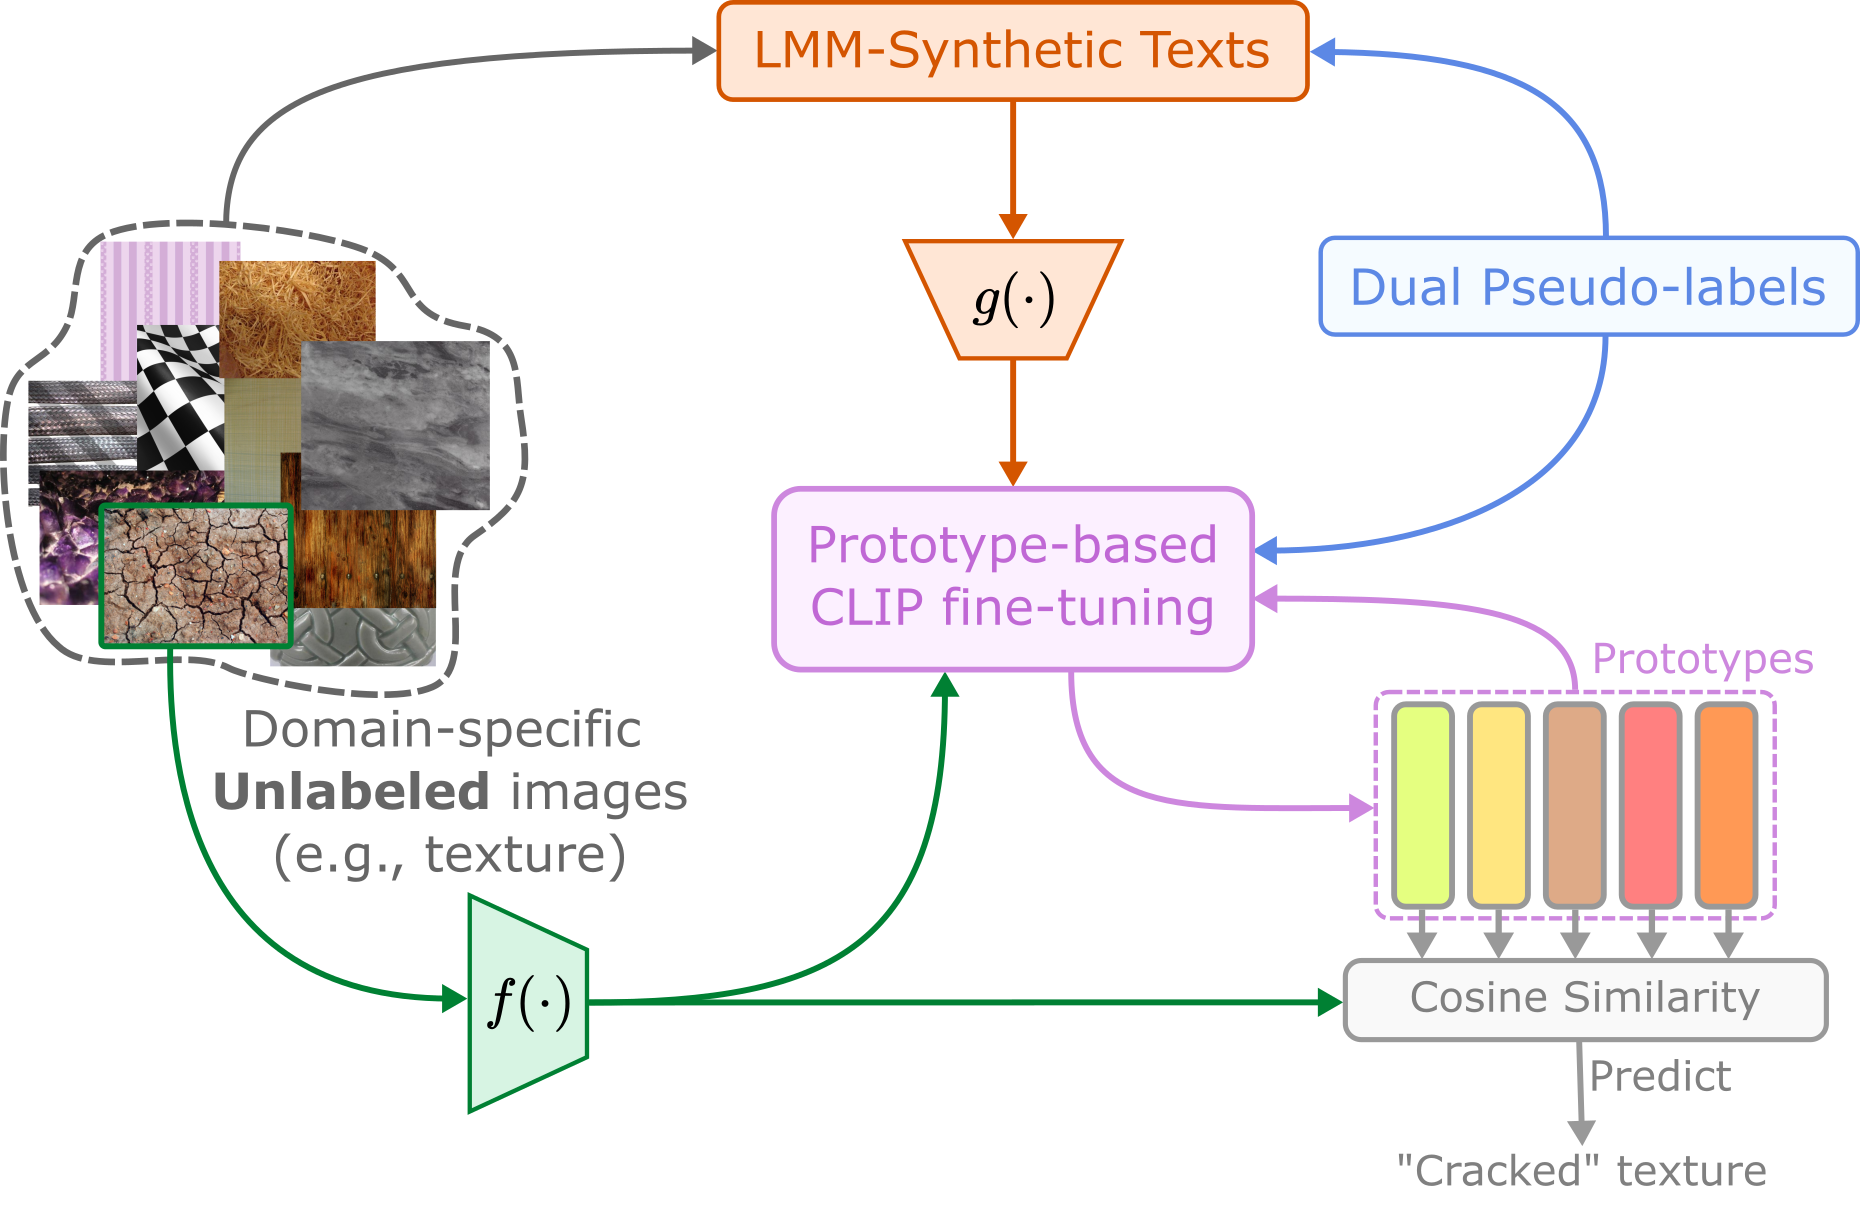
LatteCLIP: Unsupervised CLIP Fine-Tuning via LMM-Synthetic Texts

LatteCLIP: Unsupervised CLIP Fine-Tuning via LMM-Synthetic Texts

Anh-Quan Cao, Maximilian Jaritz, Matthieu Guillaumin, Raoul de Charette, Loris Bazzani
WACV 2025

TL;DR: Unsupervised CLIP adaptation using LMM-generated captions and distillation, enabling domain-specific improvements without manual labels.

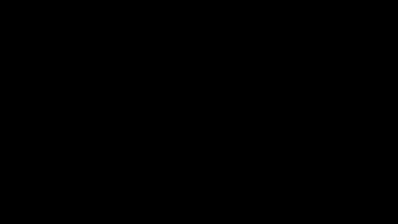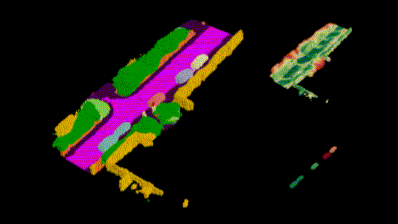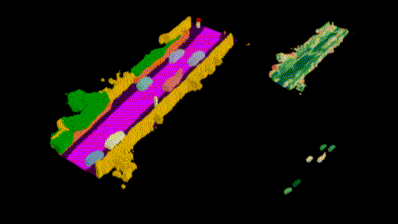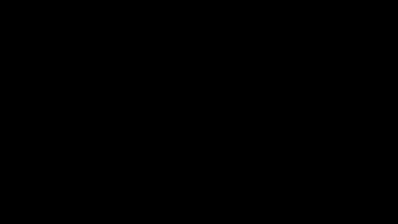
PaSCo: Urban 3D Panoptic Scene Completion with Uncertainty Awareness

PaSCo: Urban 3D Panoptic Scene Completion with Uncertainty Awareness

Anh-Quan Cao, Angela Dai, Raoul de Charette
CVPR 2024
Oral, Best Paper Award Candidate

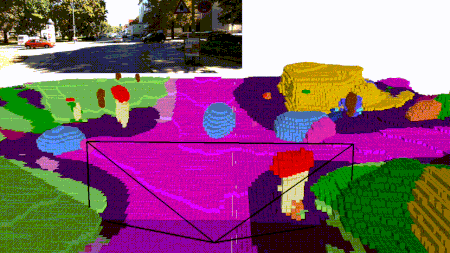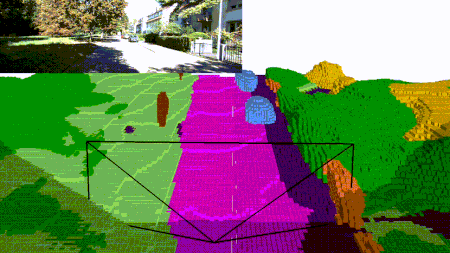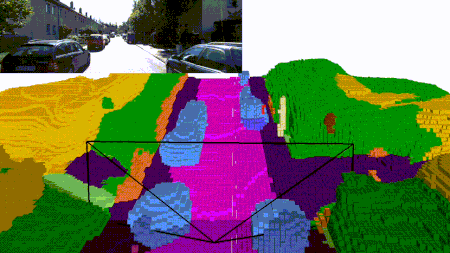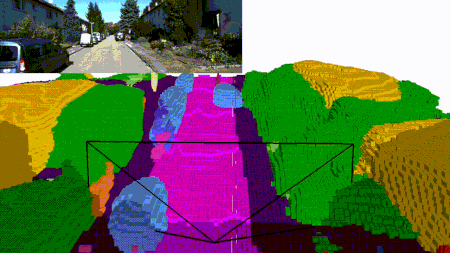
TL;DR: Introduces urban panoptic scene completion with uncertainty awareness, jointly predicting semantic voxels and object instances in 3D.

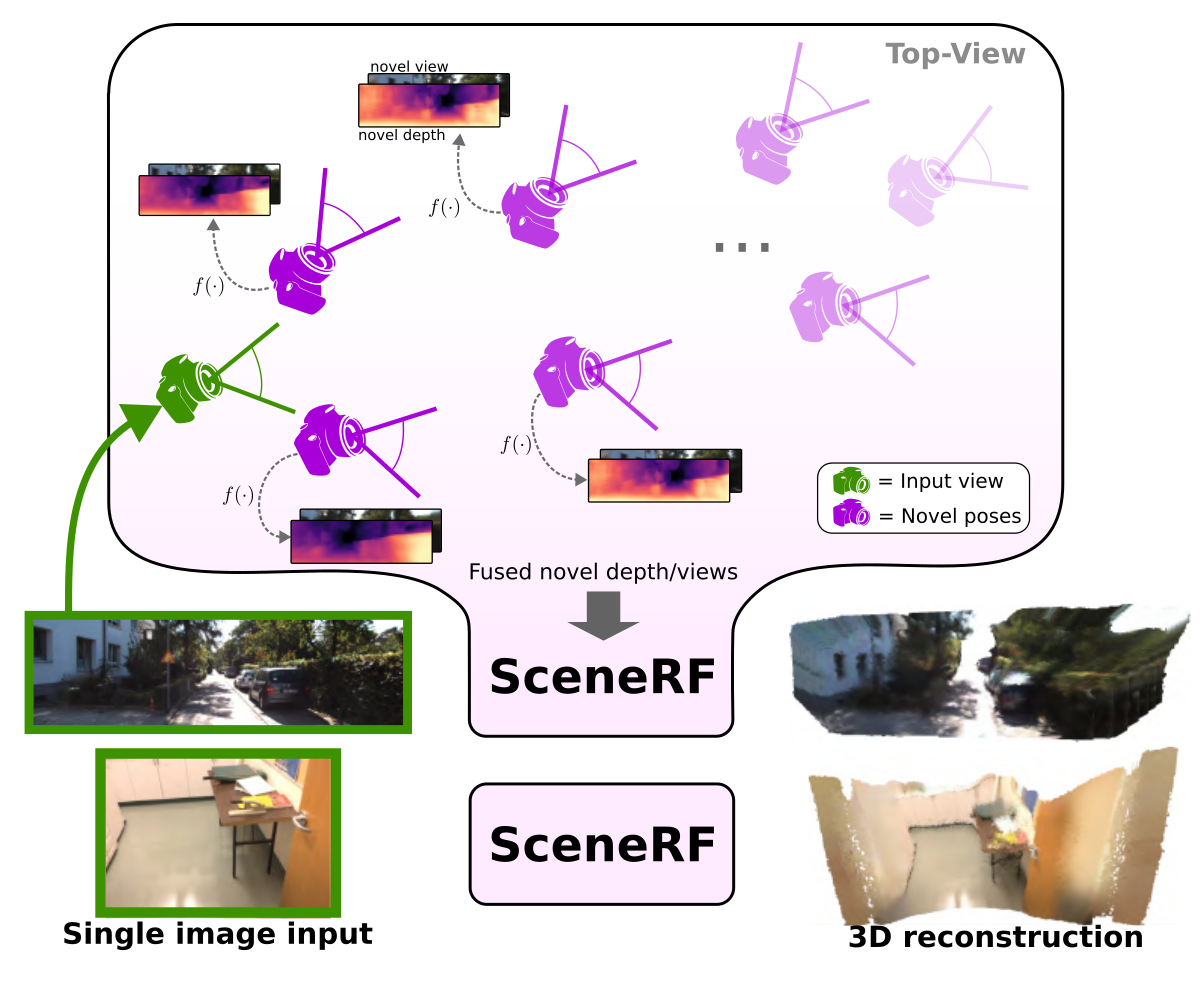
SceneRF: Self-Supervised Monocular 3D Scene Reconstruction with Radiance Fields

SceneRF: Self-Supervised Monocular 3D Scene Reconstruction with Radiance Fields

Anh-Quan Cao, Raoul de Charette
ICCV 2023

TL;DR: Self-supervised monocular 3D reconstruction with radiance fields that improves geometry quality and widens reconstructed scene coverage.

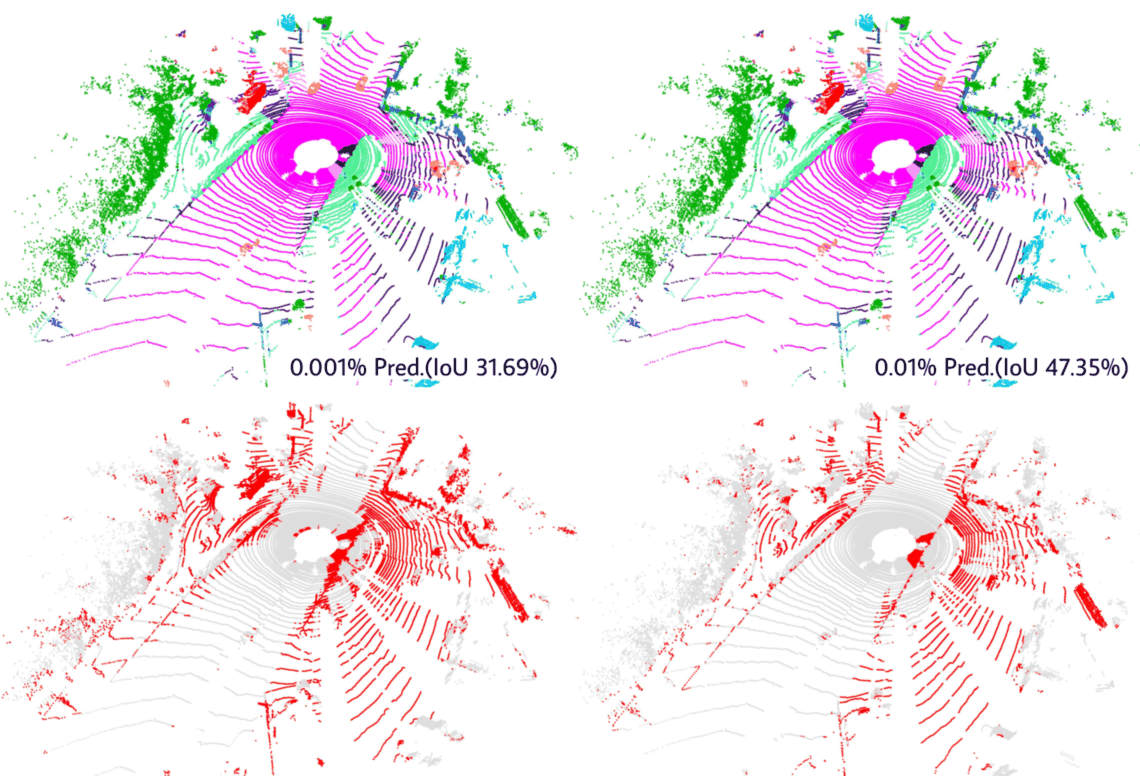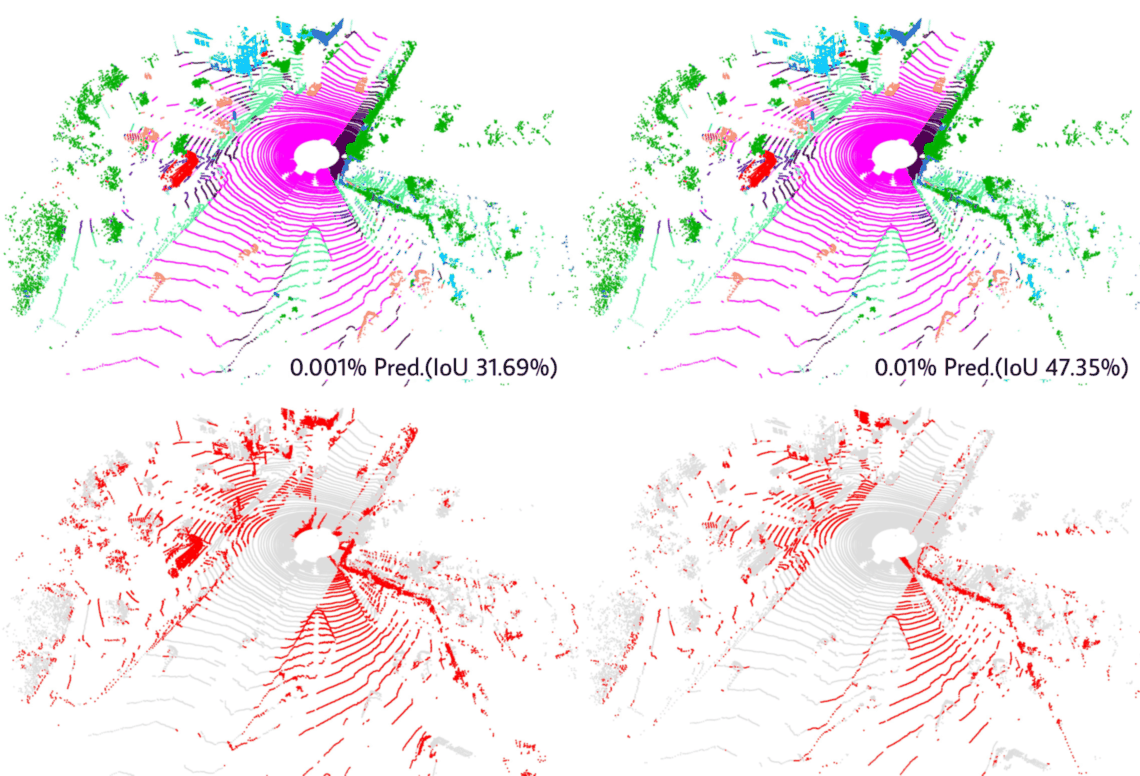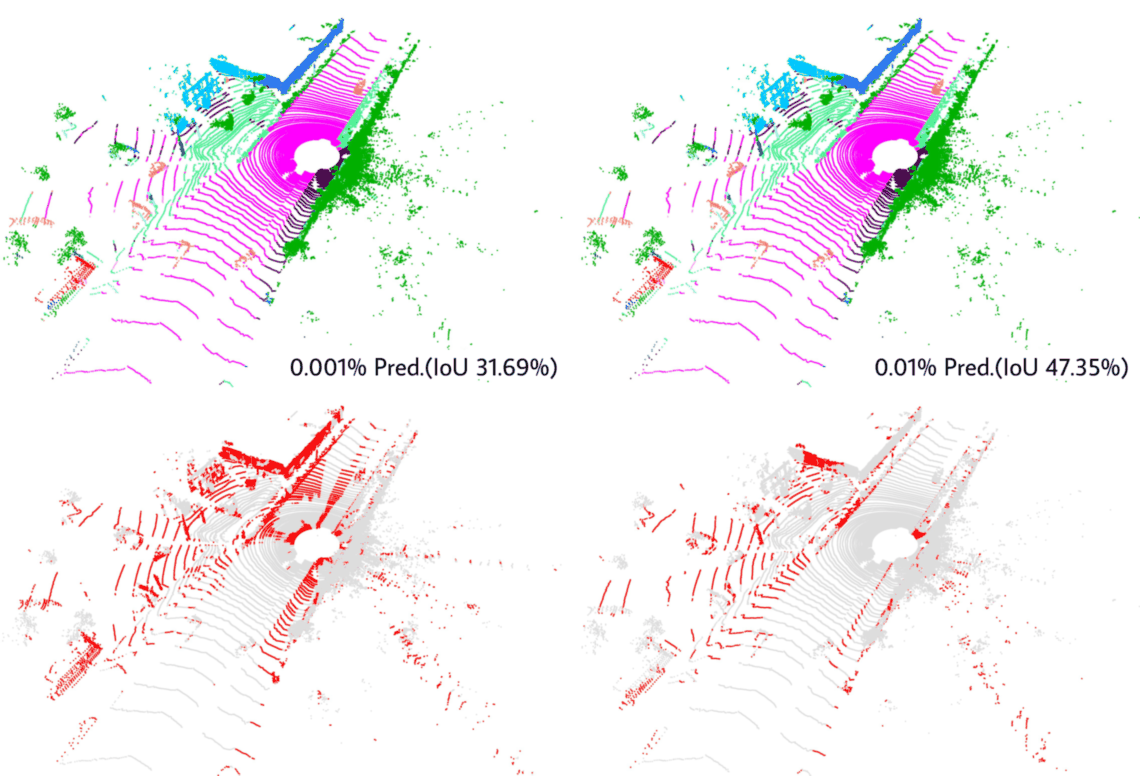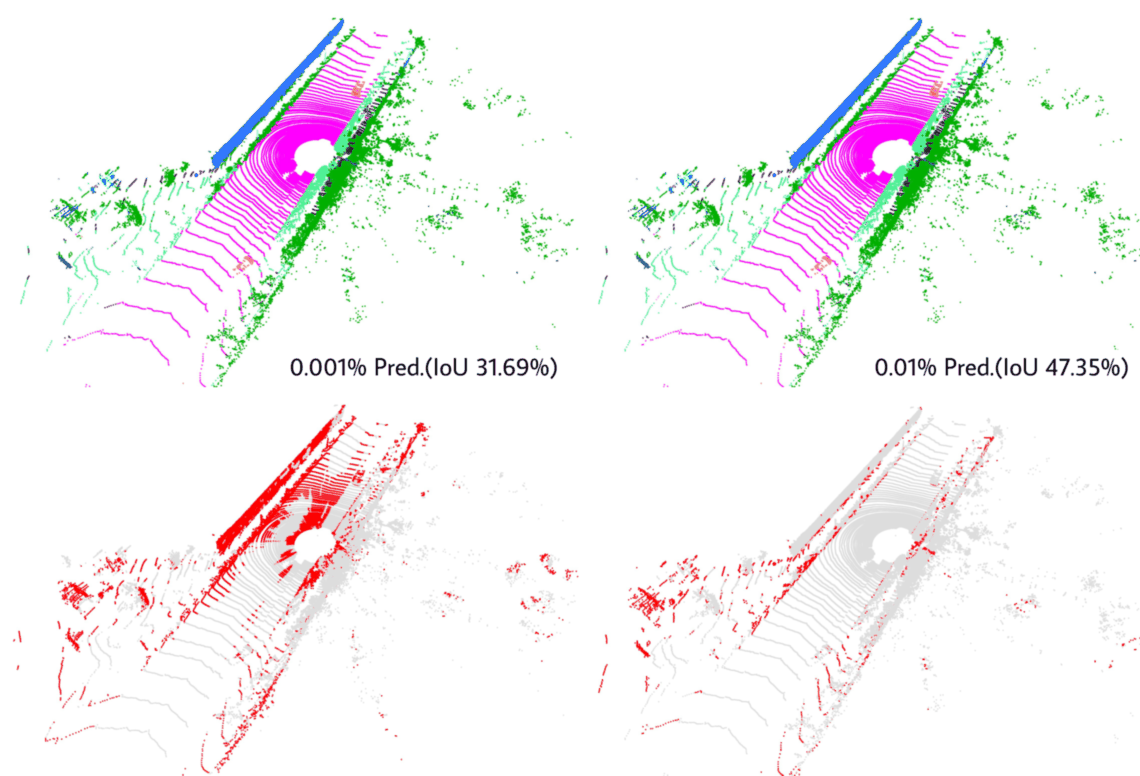
COARSE3D: Weakly-Supervised 3D Point Cloud Segmentation with Class-Prototypes

COARSE3D: Class-Prototypes for Contrastive Learning in Weakly-Supervised 3D Point Cloud Segmentation

Rong Li, Anh-Quan Cao, Raoul de Charette
BMVC 2022

TL;DR: Weakly supervised 3D point cloud segmentation with class prototypes and contrastive learning, achieving strong results with extremely sparse labels.

MonoScene: Monocular 3D Semantic Scene Completion

MonoScene: Monocular 3D Semantic Scene Completion

Anh-Quan Cao, Raoul de Charette
CVPR 2022

TL;DR: Monocular semantic scene completion that lifts 2D image features into 3D and predicts full-scene geometry and semantics beyond the camera field of view.

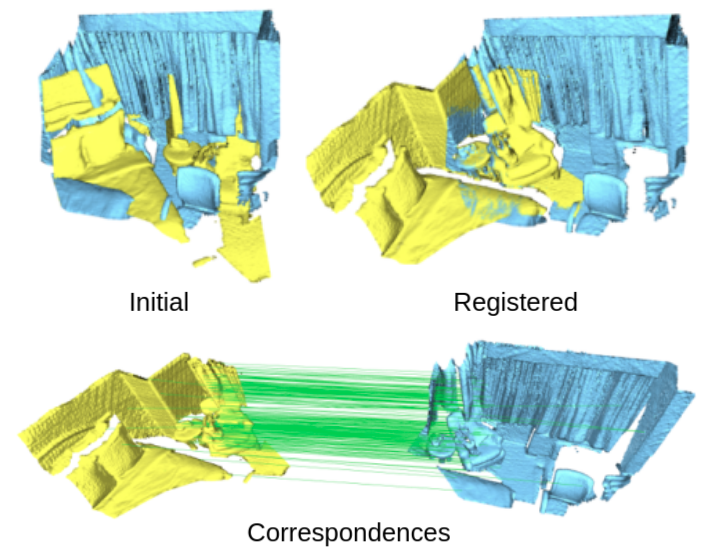
PCAM: Product of Cross-Attention Matrices for Rigid Registration of Point Clouds

PCAM: Product of Cross-Attention Matrices for Rigid Registration of Point Clouds

Anh-Quan Cao, Gilles Puy, Alexandre Boulch, Renaud Marlet
ICCV 2021

TL;DR: Rigid point cloud registration via products of cross-attention matrices, improving correspondence quality under partial overlap.

Academic services

Conference Reviewer

2026
CVPR Outstanding ECCV Outstanding
2025
WACV Outstanding CVPR Outstanding ICCV Outstanding NeurIPS Top AAAI ICLR
2024
CVPR Outstanding ECCV Outstanding ACCV
2023
WACV CVPR ICCV

Journal Reviewer

2025
TPAMI
2024
TGCV TPAMI
2023
Pattern Recognition ACM MM